Connect fragmented ERPs, CRMs, APIs, IoT sensors, and transactional databases into
self-healing, automated data pipelines built on Apache Spark, Delta Lake, and Microsoft Fabric.
Log-Based CDC IngestionMedallion Delta ArchitectureAutomated Data Quality & SLA
99.9%Pipeline execution reliability with self-healing retry logic and alerting.
< 5 MinsNear real-time data freshness with log-based Change Data Capture (CDC).
3 LayersGoverned Bronze, Silver, and Gold Medallion architecture with schema validation.
100%Traceable column-level lineage and automated data quarantine framework.
Engineering Before Reporting
Dashboards are only as dependable as the data supply
chain.
When executives question dashboard numbers, the root cause is rarely the visualization. It
is almost always upstream: brittle scripts that silently fail, unhandled schema drift, delayed night
batches, and unverified data logic.
At DAVIZ Solutions, we treat data engineering as a mission-critical software engineering
discipline. We build resilient pipelines with automated data testing, schema contracts, idempotent
ingestion, and comprehensive observability so your business operations run on trusted facts.
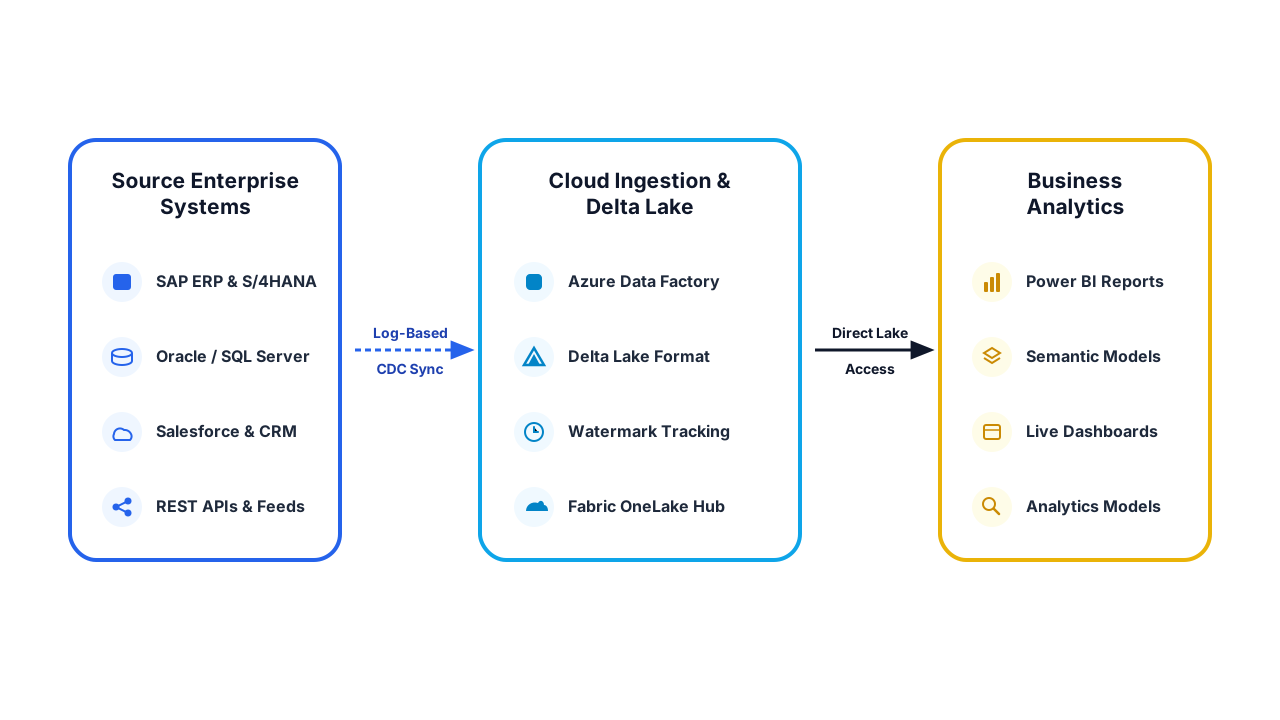
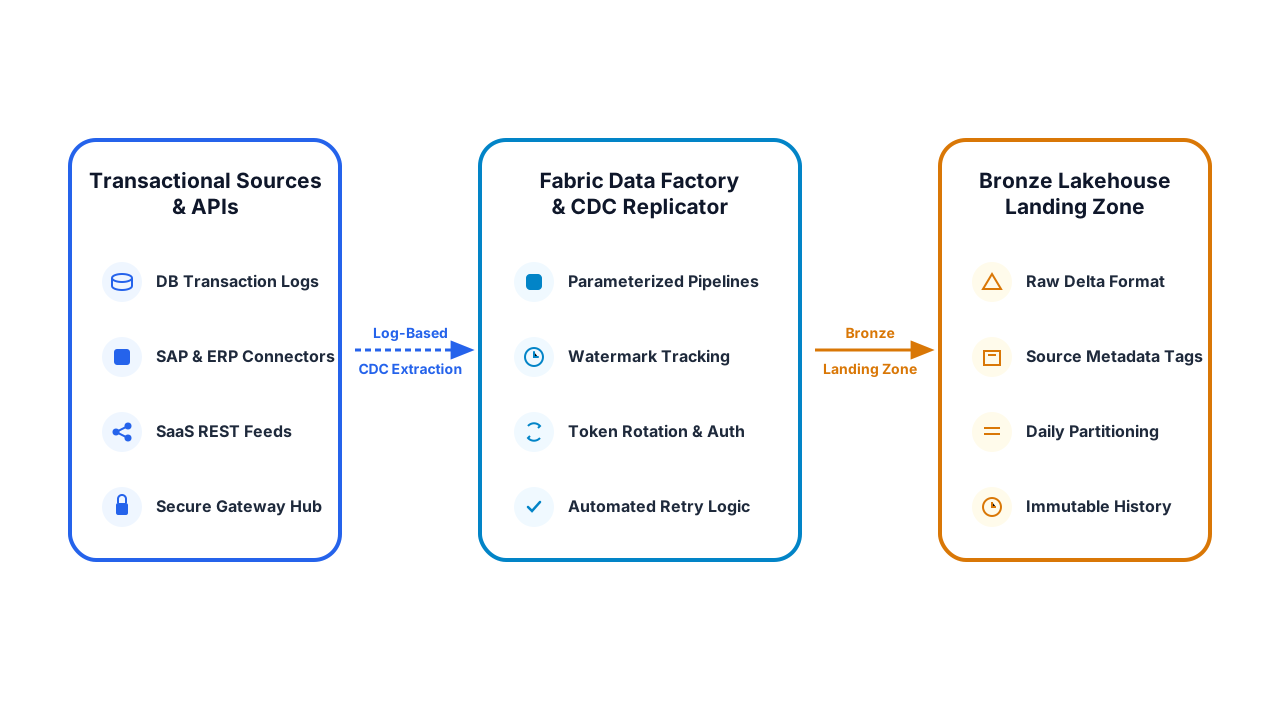
Ingest high-frequency transactional data from SQL Server, Oracle, SAP, and Postgres directly from
transaction logs without impacting source production system performance or CPU.
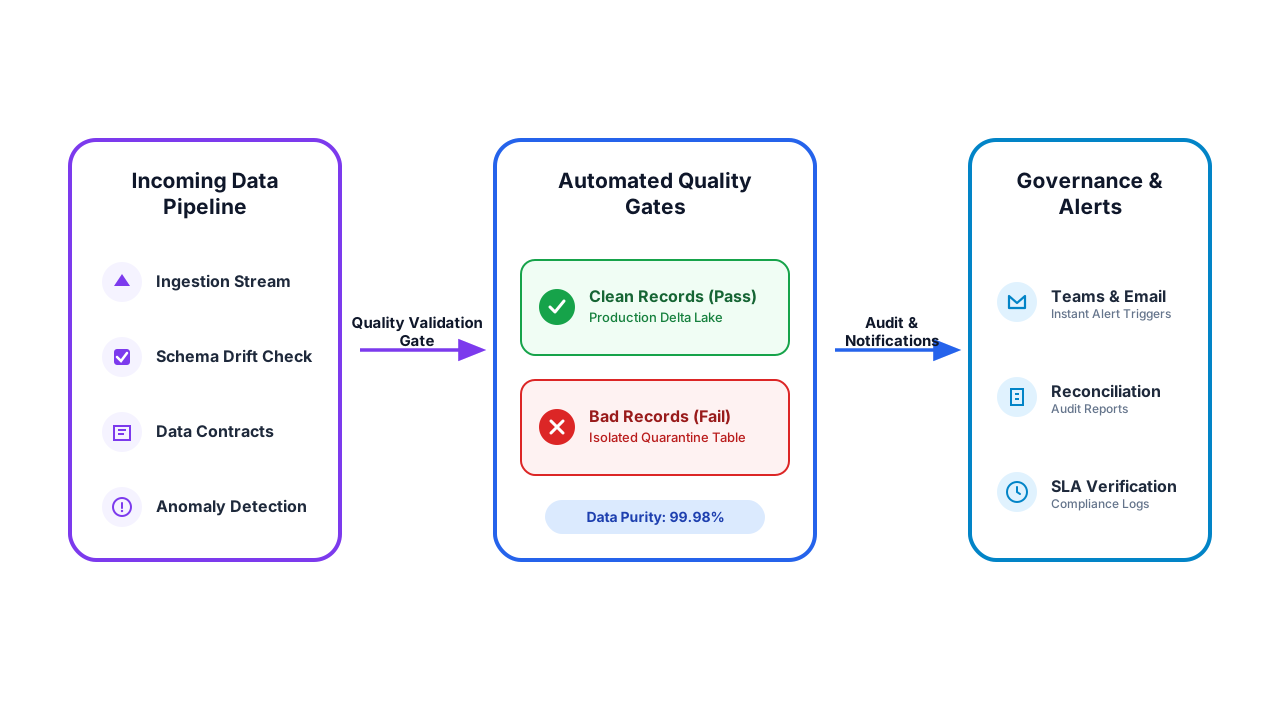
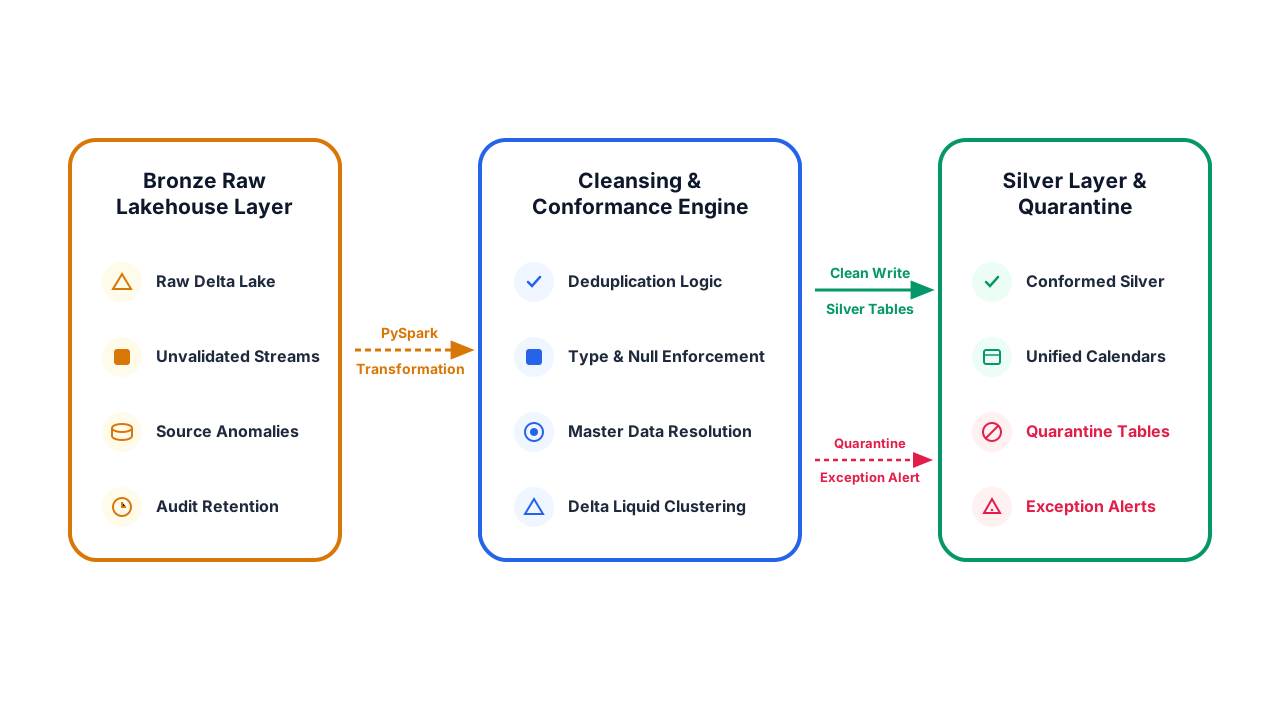
Enforce data contracts at ingestion. Invalid records, missing foreign keys, and corrupted rows are
automatically routed to quarantine tables while clean data flows to Gold reporting uninterrupted.
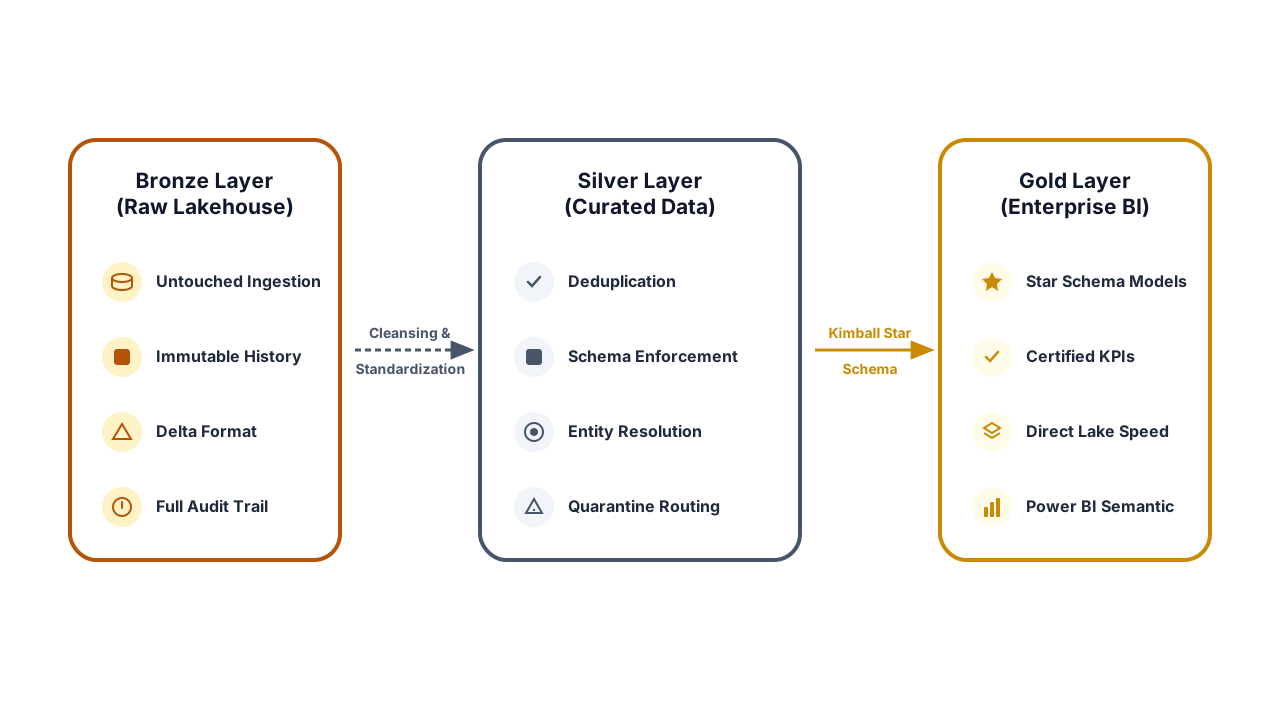
Separate raw landing data (Bronze) from conformed business entities (Silver) and curated dimensional
models (Gold) using Delta Lake open Parquet storage with time-travel and rollback capabilities.
Process multi-terabyte datasets in minutes. We write optimized PySpark notebooks, configure dynamic
executor allocation, and apply liquid clustering and V-Order indexing for lightning-fast reads.
Track pipeline freshness SLAs, execution durations, compute costs, and schema drift with automated
Microsoft Teams and email alerts before business stakeholders ever detect a delay.
Engineering Disciplines
From Source Ingestion to Certified Enterprise Data
Products.
Our certified engineers implement production-grade frameworks designed to withstand
real-world operational chaos and API volatility.
Change Data Capture (CDC) & Enterprise Connectors
Modern data pipelines cannot rely on nightly full-table dumps that overload transactional databases.
We implement low-latency log-based CDC across Microsoft SQL Server, Oracle, SAP ERP, Salesforce, and
Dynamics 365. Incremental changes (inserts, updates, deletes) are synchronized continually with zero
operational impact on your core business systems.
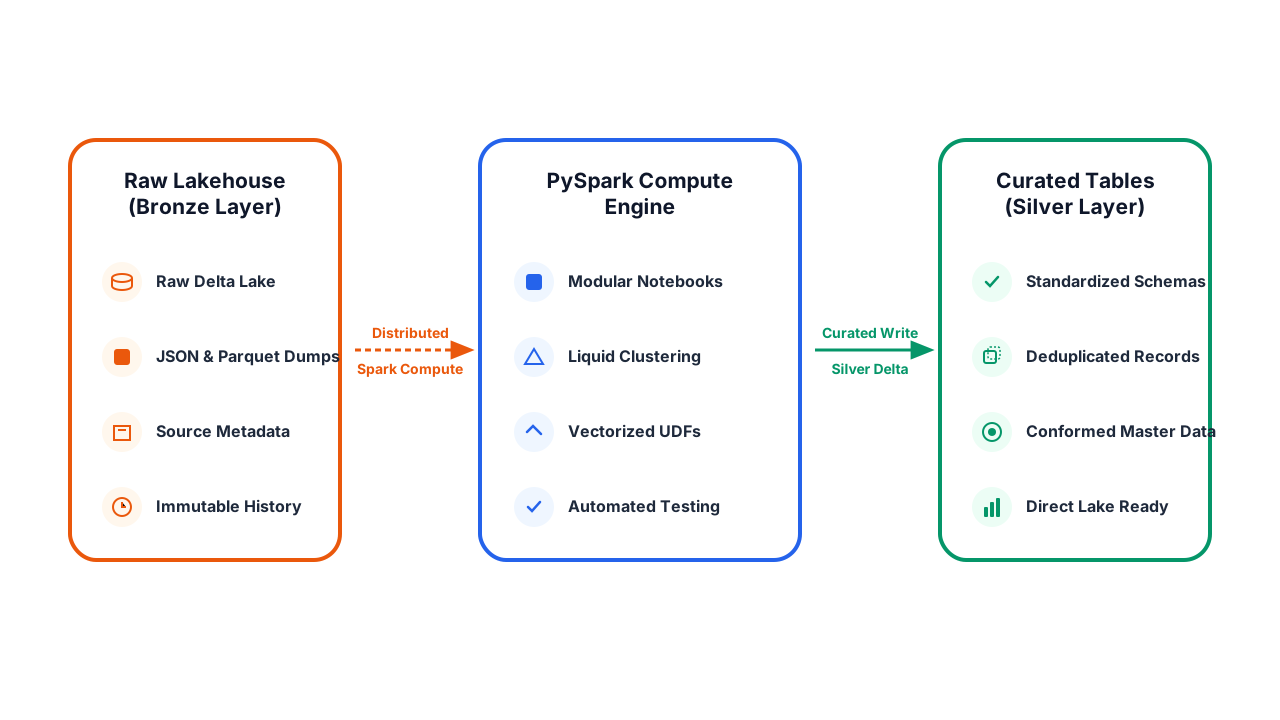
When dataset volumes exceed billions of rows, traditional single-node ETL tools break down. Our teams
build scalable, distributed data processing jobs using Apache Spark and PySpark. We implement modular
notebook frameworks, automated unit tests, reusable helper libraries, and Git-controlled code
versioning for seamless team collaboration.
We architect strict Medallion separation to ensure data integrity and full auditability.
Bronze preserves raw, immutable source history. Silver standardizes,
cleanses, deduplicates, and resolves master customer/vendor identities. Gold builds
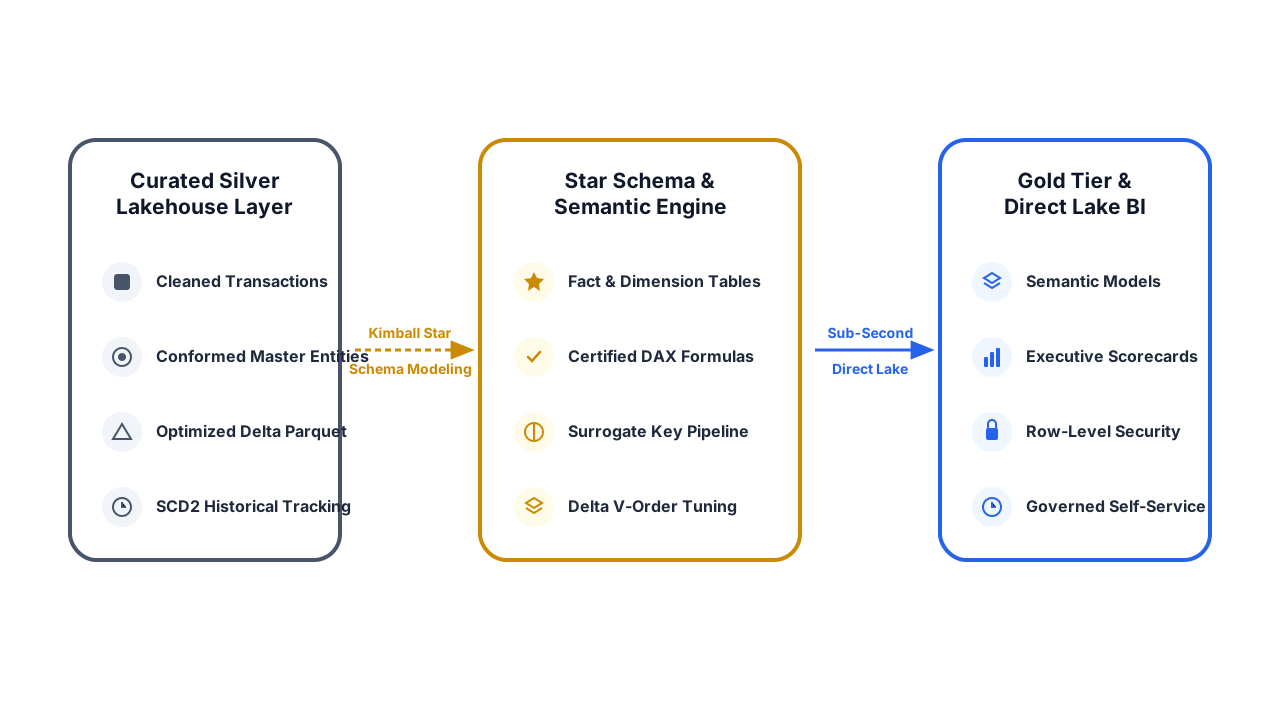
star-schema dimensional models optimized for sub-second Direct Lake Power BI queries.
Automated Data Quality & Quarantine Frameworks
Never let corrupted data pollute executive reports. We build proactive data quality gates into every
transformation pipeline. Using schema enforcement, uniqueness checks, referential integrity
validation, and statistical anomaly detection, bad records are automatically diverted into isolated
quarantine tables with automated alert notifications.
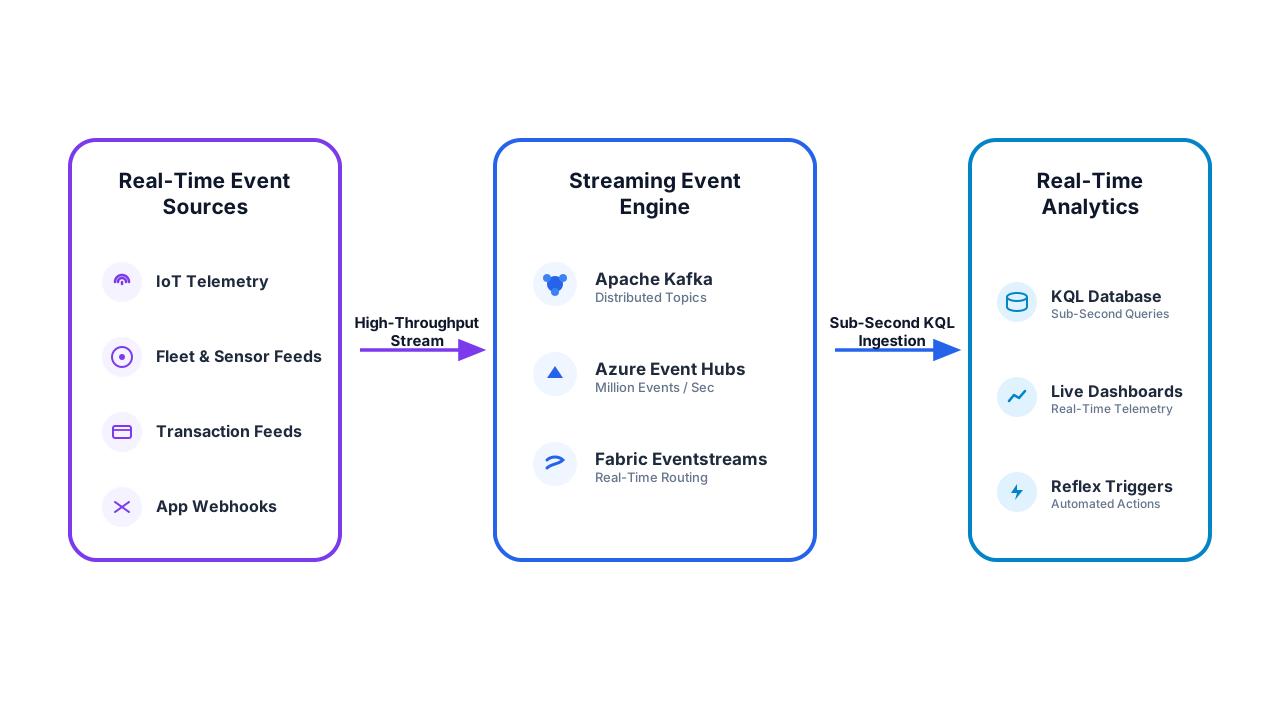
Real-Time Event Streaming & Telemetry Pipelines
For logistics fleets, manufacturing sensors, financial fraud detection, and point-of-sale
transactions, batch data is often too late. We build real-time event streaming pipelines using Azure
Event Hubs, Kafka, and Microsoft Fabric Eventstreams. Telemetry is parsed, aggregated, and stored in
KQL databases for live operational dashboards.
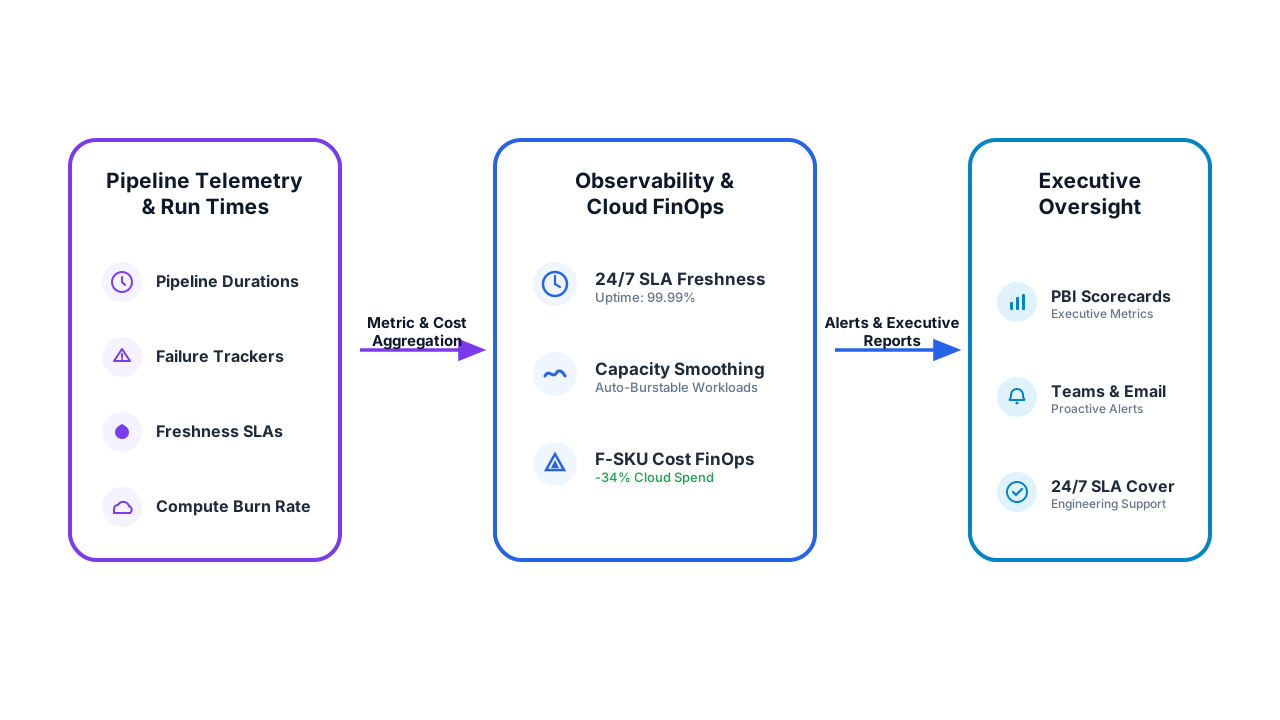
24/7 Pipeline Observability & Cloud FinOps
Maintain total operational control over your data estate. We implement centralized observability
dashboards that track pipeline run times, failure rates, data freshness SLAs, and cloud compute
expenditures. Automated anomaly alerts notify your engineers before downstream business operations are
impacted.
Technical Superiority
Legacy Stored Procedure ETL vs. Modern Medallion
Pipelines.
Understand why leading enterprises are moving away from brittle, black-box SQL scripts to
testable, scalable, and version-controlled data engineering frameworks.
✓ ACID Transactions — Atomic commits guarantee all-or-nothing
data consistency
Data Testing
✕ Post-Mortem — Discovered by end users when executive
reports show incorrect numbers
✓ In-Flight Validation — Automated schema and contract tests
quarantine bad rows upfront
Scalability
✕ Single-Node Limit — Maxes out database CPU and memory on
heavy data volumes
✓ Distributed Compute — Scales dynamically across Spark
clusters or Fabric F-SKUs
Version Control
✕ Untracked Changes — Code edited directly in database;
difficult to review or audit
✓ Full Git CI/CD — Pull request reviews, automated linting,
and promotion environments
Historical Auditing
✕ Overwritten Data — Updates overwrite historical states
unless complex SCD2 is built
✓ Delta Time Travel — Query any previous table version or
point in time instantly
Downstream BI
✕ Slow Extracts — Power BI must extract data into separate
proprietary memory models
✓ Direct Lake Ready — Power BI reads directly from open Delta
files at in-memory speed
Delivery Framework
Our 6-Stage Data Pipeline Engineering & Modernization
Process.
A disciplined engineering workflow that delivers production reliability from day one.
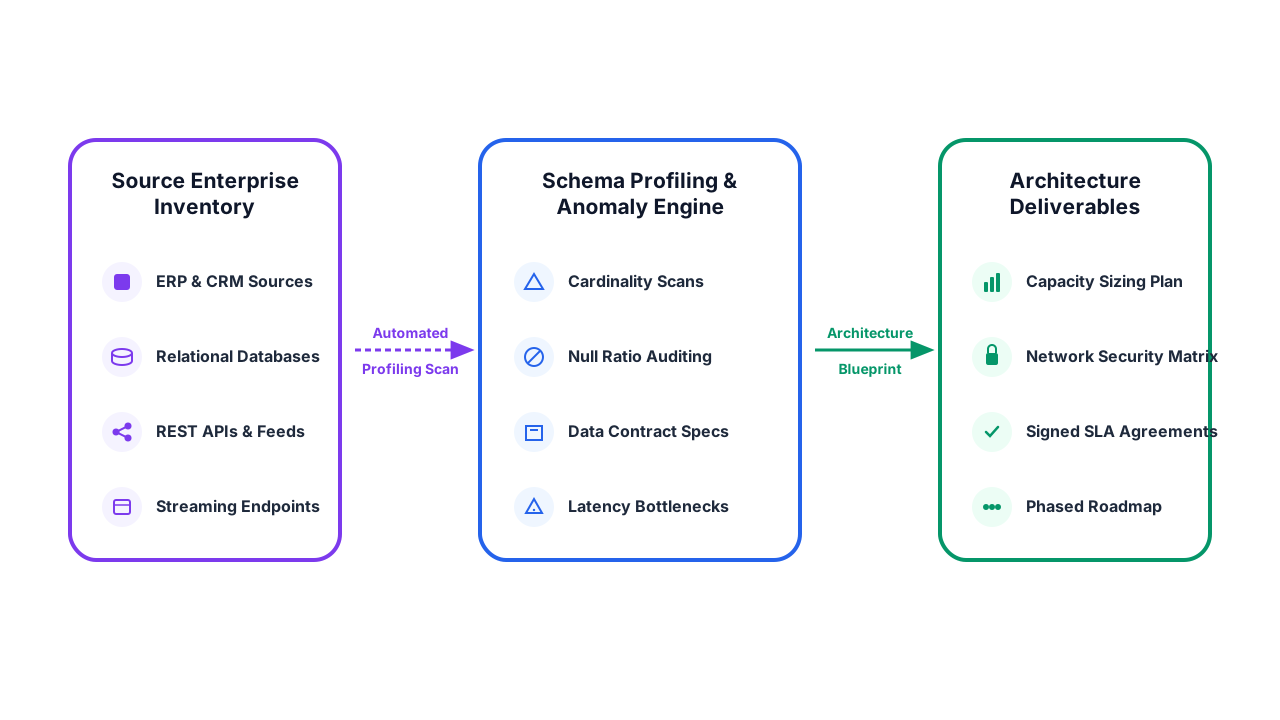
Stage 01: Discovery & Profiling
Source System Discovery & Schema Profiling
We conduct an exhaustive audit of your data sources—ERPs, transactional databases, CRM APIs, flat
files, and streaming endpoints. We profile data volumes, cardinality, null ratios, and identify
upstream bottlenecks.
We implement resilient ingestion pipelines using log-based Change Data Capture (CDC), scheduled batch
extractors, and REST API connectors with automated watermark tracking and parameter-driven retries.
We engineer PySpark transformation pipelines that cleanse corrupted characters, enforce data types,
deduplicate records, align master data entities, and route quality exceptions into quarantine tables.
We construct Kimball-standard dimensional facts and dimensions in the Gold tier. Calculation logic
for enterprise KPIs is certified and modeled for instant Direct Lake consumption in Power BI.
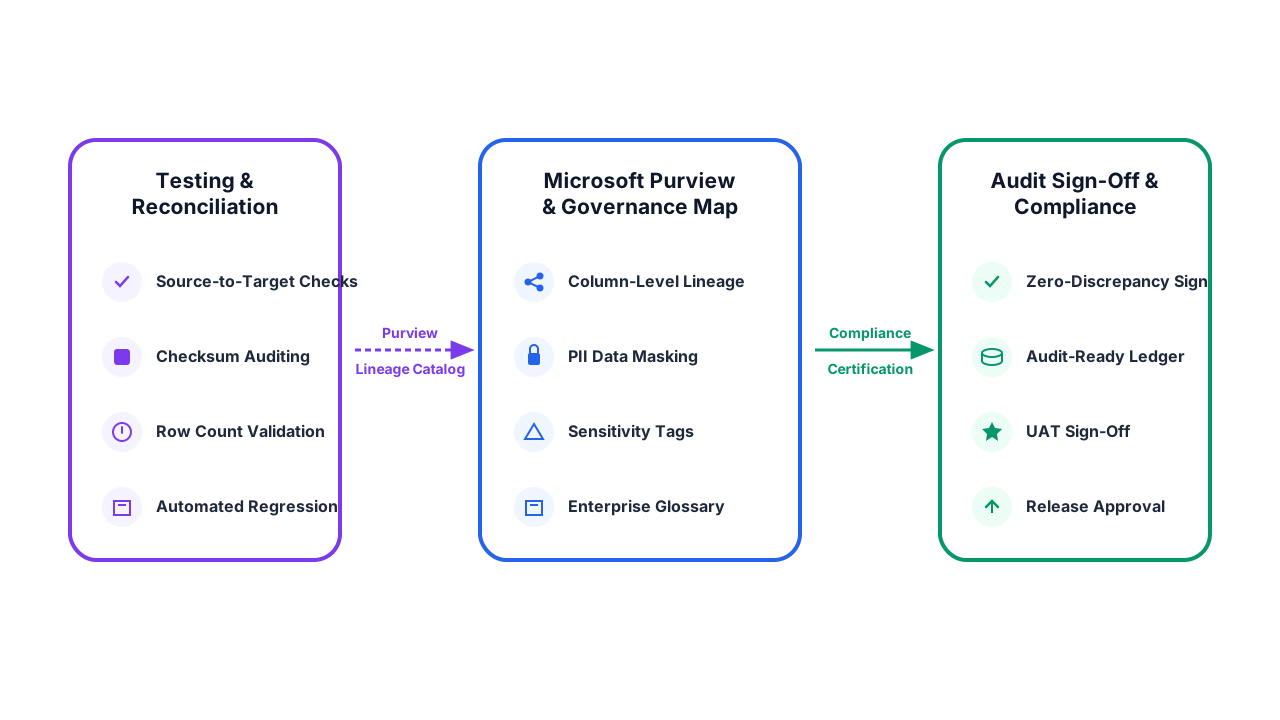
We run end-to-end data reconciliation audits comparing raw transactional sources against Gold
aggregates. Column-level lineage is cataloged in Microsoft Purview for complete compliance and audit
readiness.
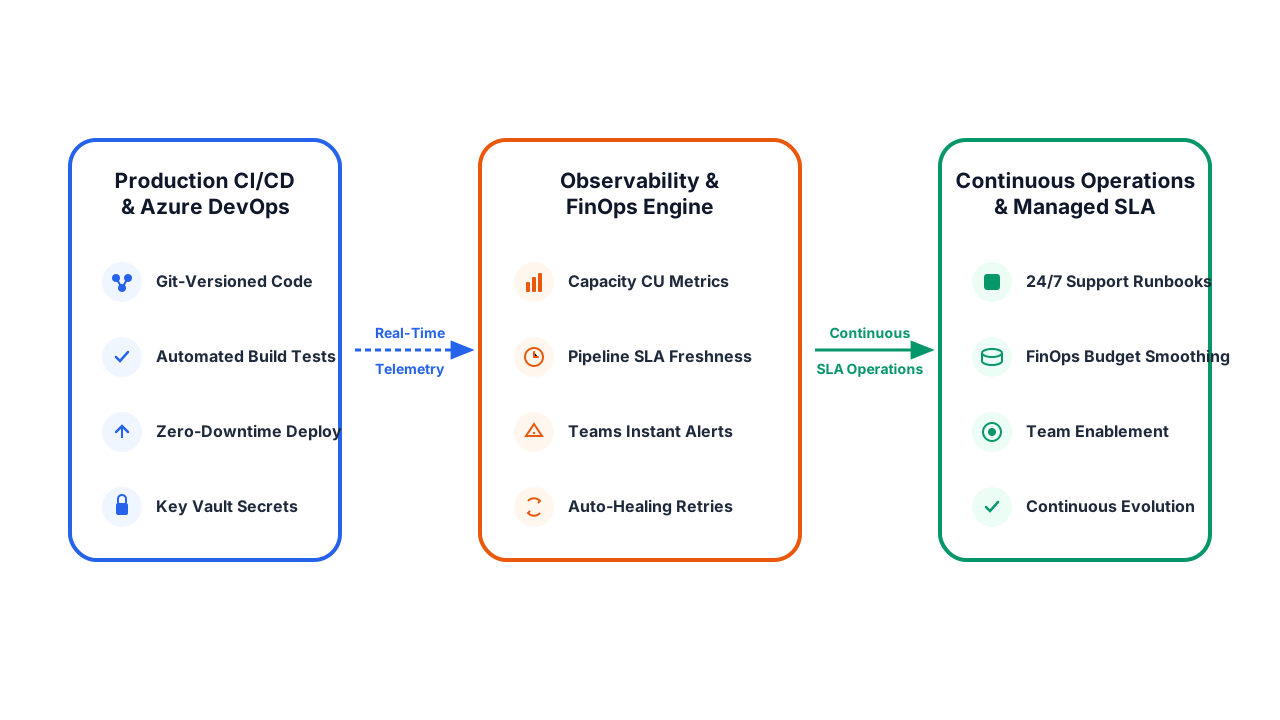
We execute parallel run cutovers, configure real-time pipeline freshness and failure alerting in
Microsoft Teams, and hand over complete operational runbooks backed by our ongoing engineering support
SLA.
Production CI/CD deployment pipelines (Azure DevOps)
Eliminate pipeline failures and data downtime today.
Connect with our senior data engineers in Dubai. We will review your current pipeline architecture,
diagnose your latency bottlenecks, and deliver a clear plan.
Traditional batch pipelines execute large queries (e.g.
SELECT * WHERE updated_at > yesterday) which scan entire database tables, locking rows,
causing query timeouts, and straining CPU on production ERPs. Change Data Capture (CDC)
reads directly from the database transaction log (like SQL Server transaction log or Oracle redo log). It
captures every row insert, update, and delete in near real time with virtually zero CPU overhead, enabling
sub-5-minute data freshness without impacting operational systems.
The Medallion architecture enforces strict quality gates across three tiers:
• Bronze (Raw): Exact, immutable mirror of source data with metadata audit stamps.
• Silver (Cleansed): Cleansed, deduplicated, and conformed enterprise data with
schema validation and business rule checks. Records failing validation are automatically routed to
quarantine.
• Gold (Business-Ready): Star-schema dimensional marts and aggregated KPIs certified
for executive Power BI consumption and machine learning.
Yes. Legacy SSIS packages and nested SQL stored procedures are notorious for lack of version control,
difficult debugging, and poor horizontal scalability. We reverse-engineer your existing business logic,
map out source-to-target data dependencies, and rebuild the workflows as parameterized, testable PySpark
notebooks or Fabric Dataflow Gen2 pipelines with full Git CI/CD integration.
Schema drift occurs when source application updates alter column types, rename fields, or add new columns
without warning. We build automated schema contracts into ingestion pipelines using Delta Lake schema
evolution and Great Expectations. When a critical schema violation occurs, the pipeline catches the drift,
logs an alert, quarantines the affected payload, and prevents downstream model corruption.
We apply several architectural best practices:
1. Liquid Clustering & Z-Order: Organizes Parquet files along high-cardinality
filter columns to maximize file skipping during query execution.
2. Delta V-Order: Microsoft Fabric optimization that applies dictionary and
run-length encoding for in-memory read speeds matching VertiPaq.
3. Auto-Compaction: Automatically merges small 10MB files into optimal 128MB–1GB
Parquet files to eliminate the small-file overhead.
For ongoing managed pipeline engagements, we provide a structured Service Level Agreement (SLA) with
guaranteed 15-minute emergency incident response times for critical production pipelines, 24/7 automated
telemetry monitoring, monthly capacity FinOps reviews, and dedicated senior data engineering leads.